Geometric Alignment
Geometric Parallax Rectification predicts bounded offsets and masks to align event features with RGB structure.
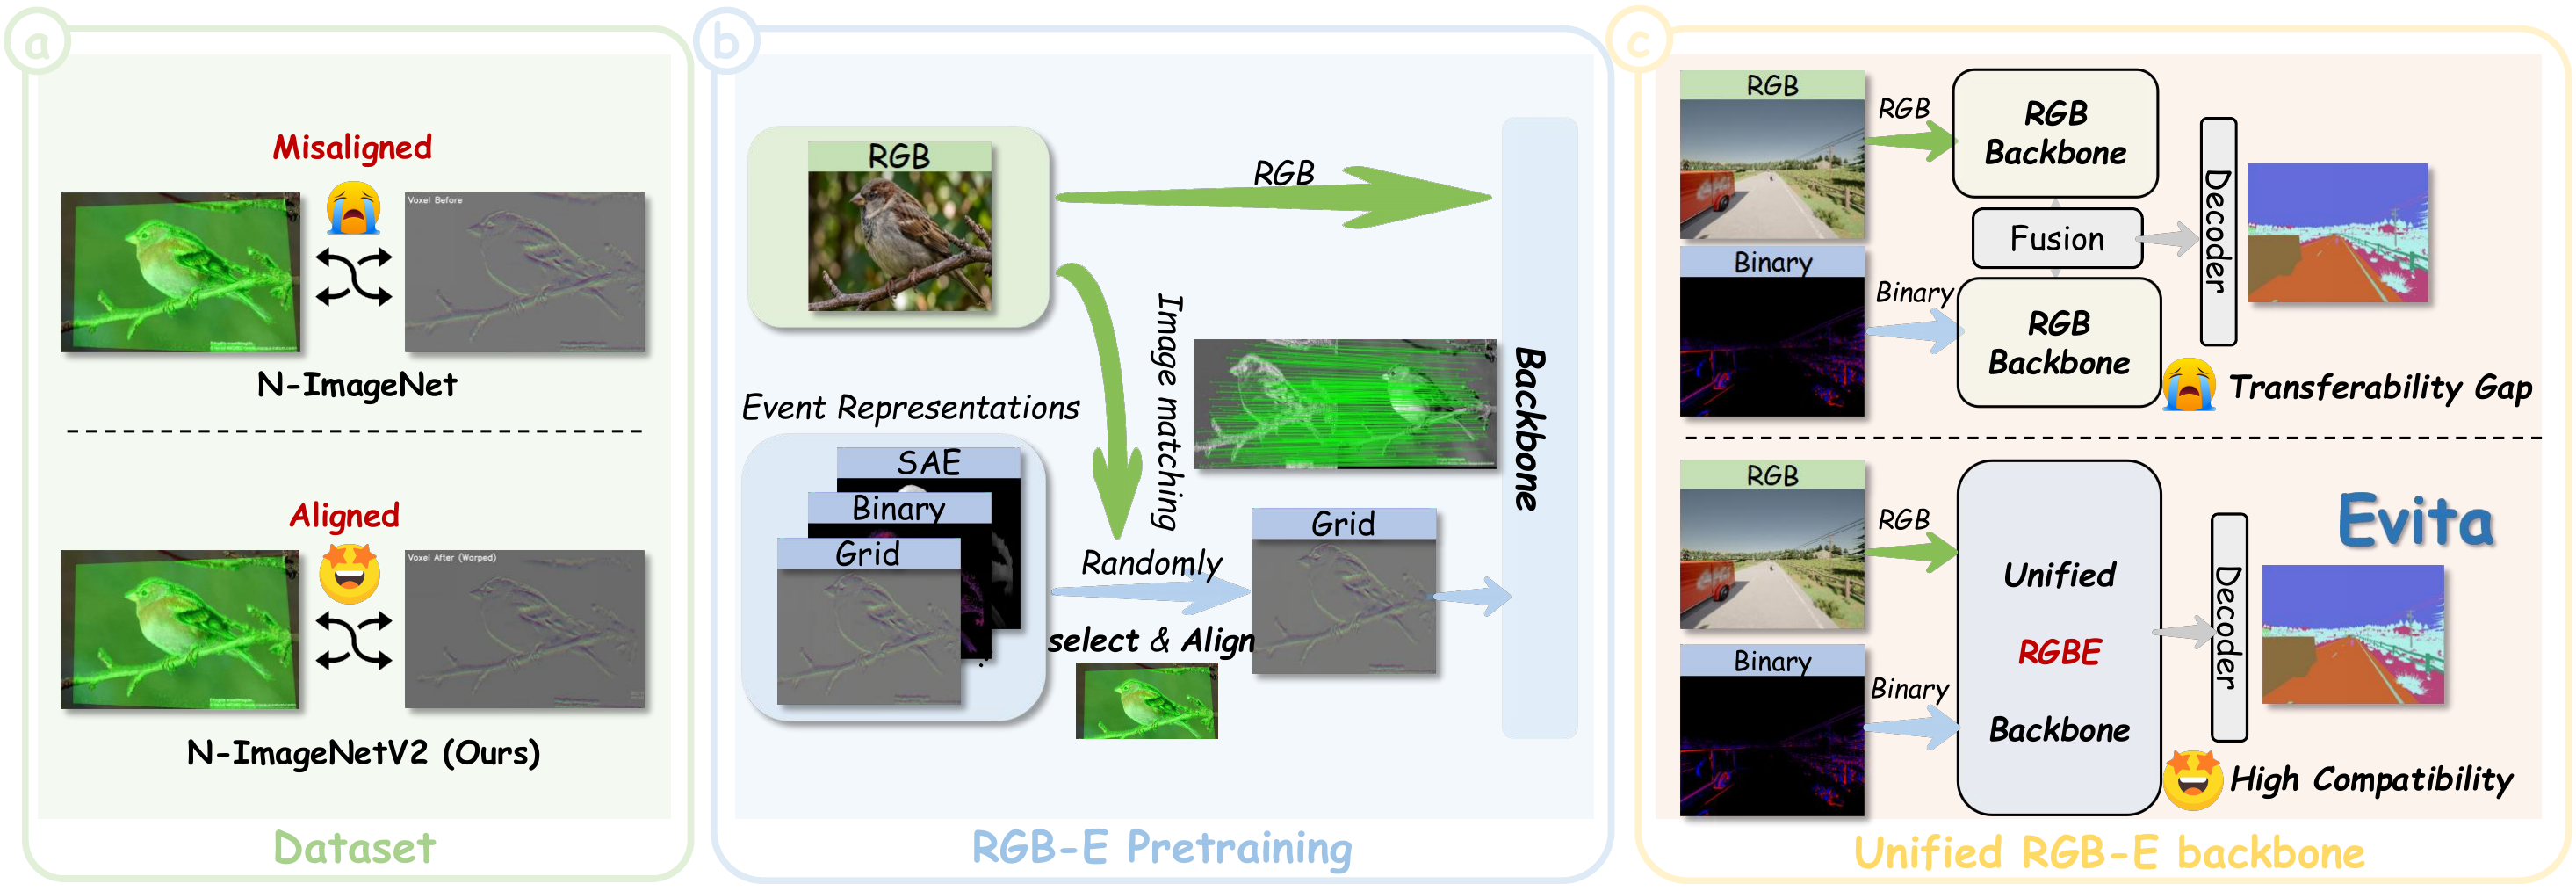
Evita is a unified RGB-Event backbone for robust dense perception in motion blur, low light, adverse weather, and other challenging real-world scenes.
Evita starts from a simple observation: RGB frames and event streams are complementary, but they are not naturally aligned in space, time, or representation. The framework therefore addresses dataset alignment, event-format pretraining, and unified RGB-Event feature learning together.
The Evita block embeds geometric, spectral, and routing operations inside the encoder itself. This makes RGB-Event interaction an intrinsic part of representation learning rather than a late-stage decoder operation.
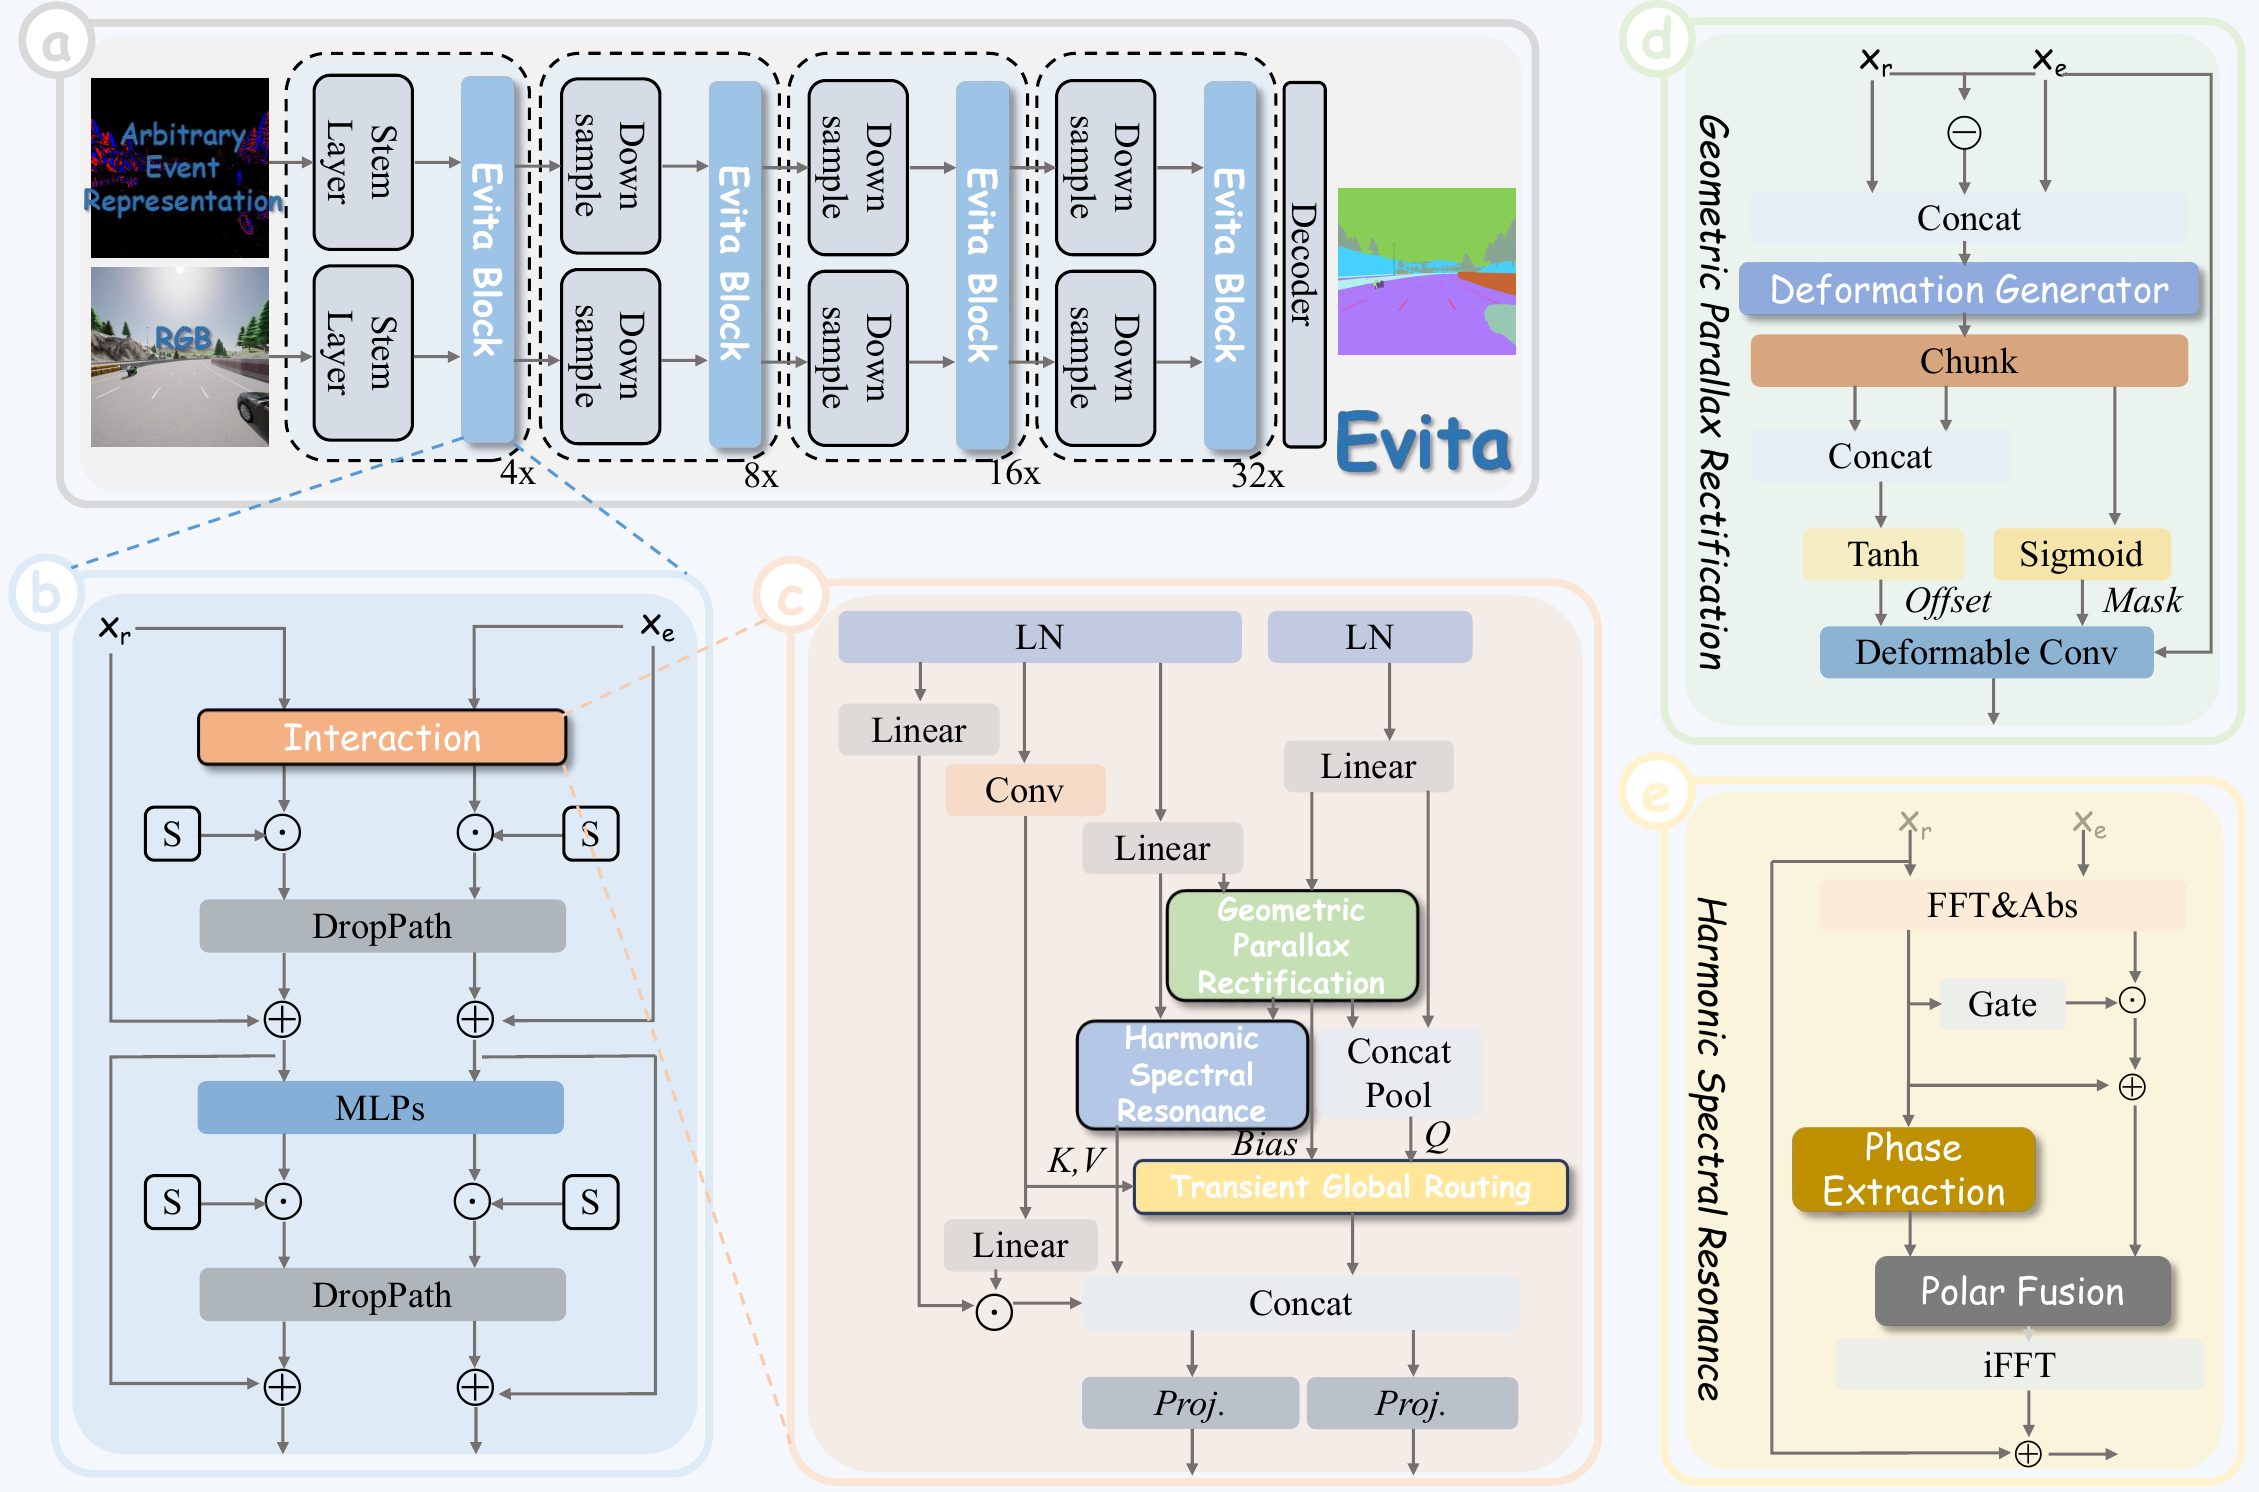
Geometric Parallax Rectification predicts bounded offsets and masks to align event features with RGB structure.
Harmonic Spectral Resonance moves event-driven high-frequency cues through the frequency domain while preserving RGB phase information.
Transient Global Routing uses event features as dynamic queries to gather global photometric context from the RGB stream.
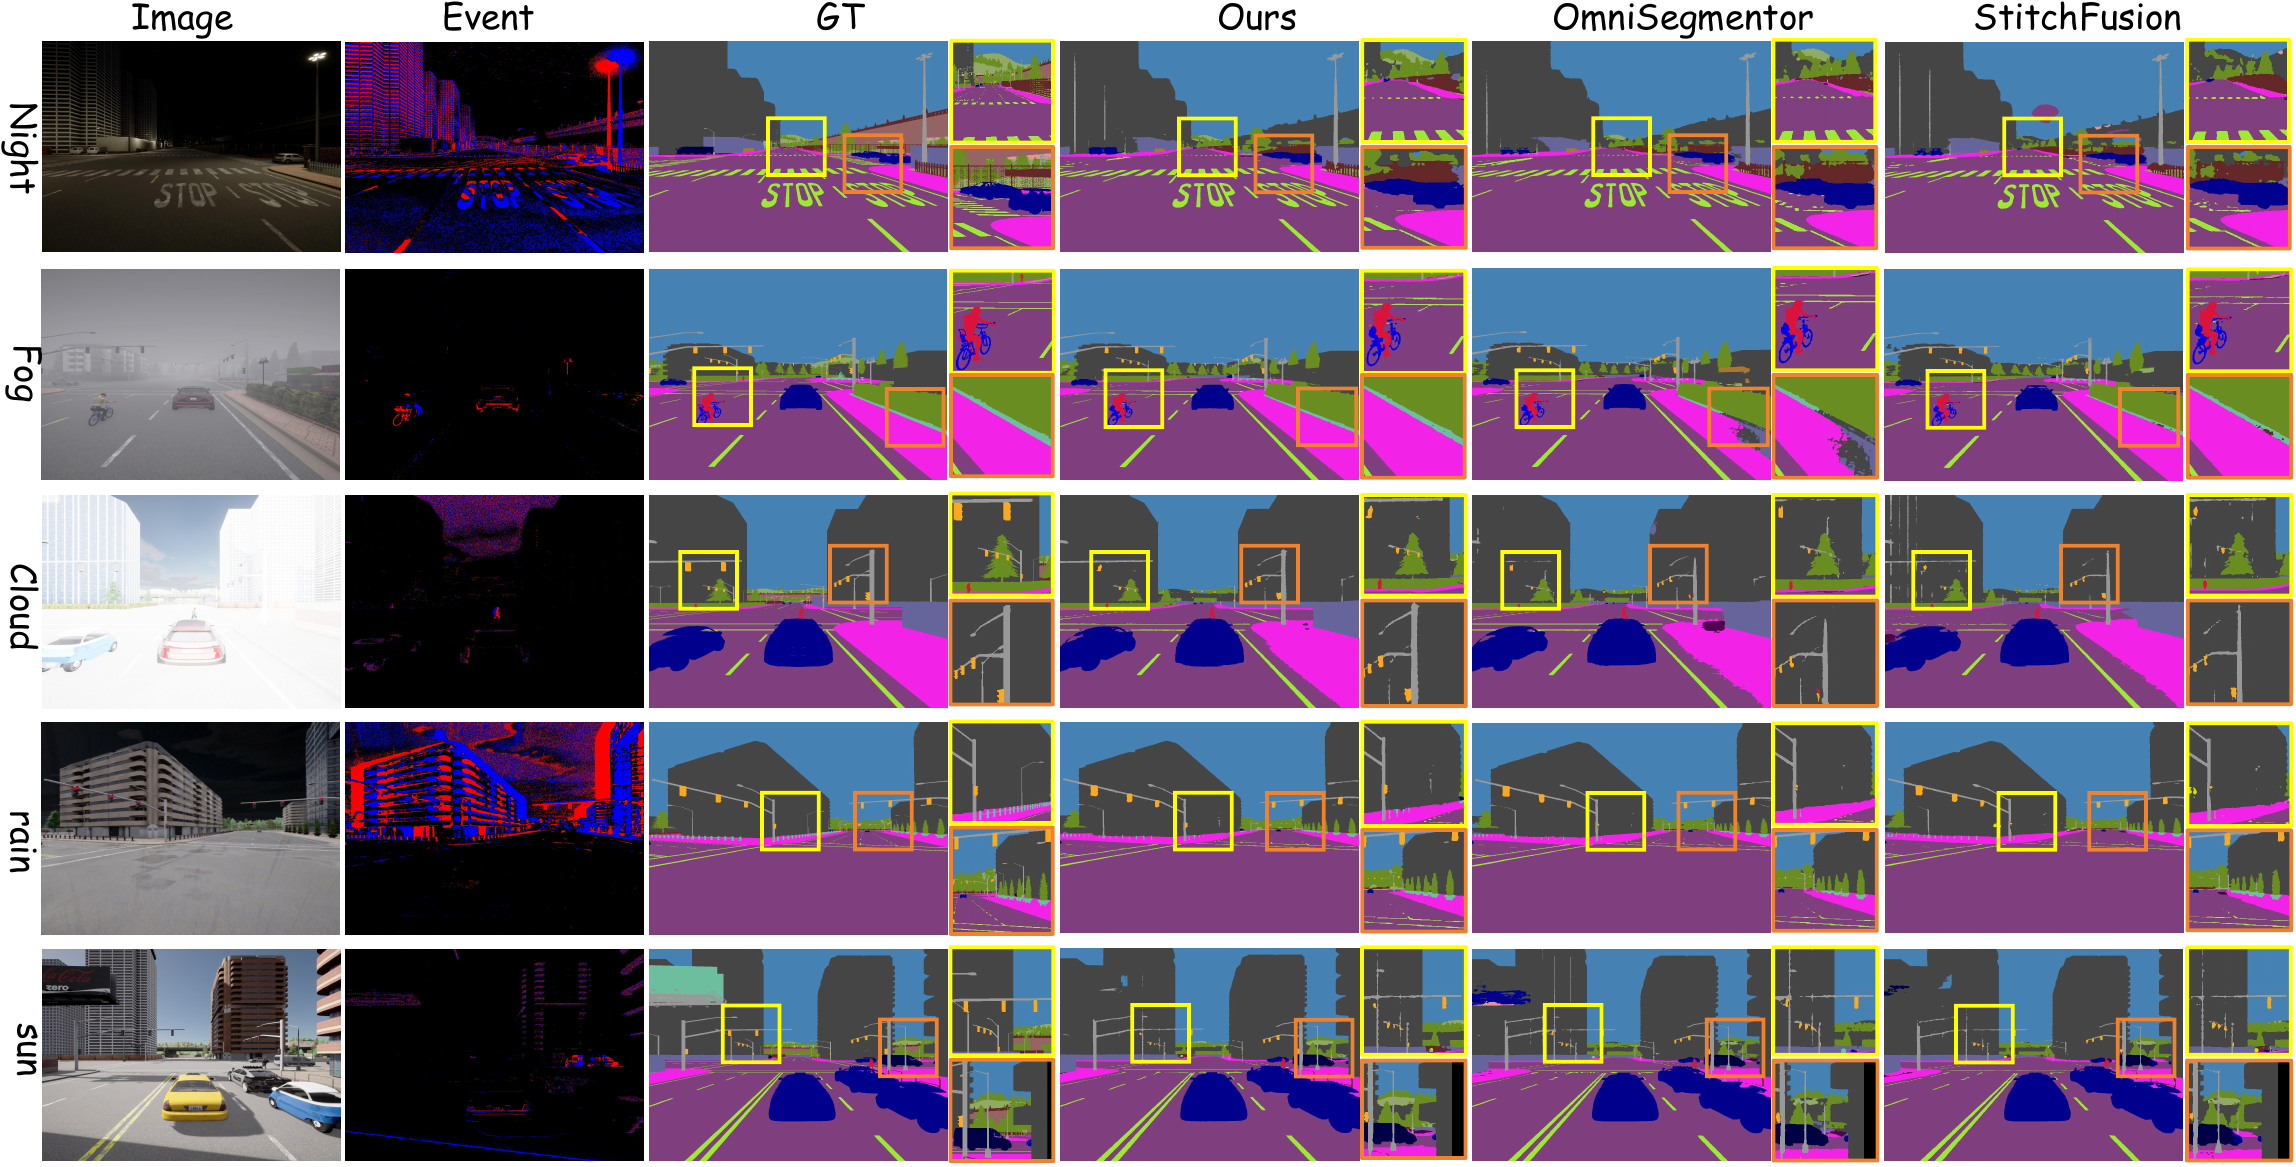
Across night, fog, cloudy, rainy, and sunny scenes, Evita produces cleaner dense parsing around thin structures, road boundaries, vehicles, and low-visibility regions. The qualitative comparison highlights that event cues are most useful when RGB alone becomes unreliable.
The accuracy-FLOPs curve further shows why a unified backbone matters: Evita reaches strong mIoU while avoiding the redundant computation of large dual-stream pipelines.
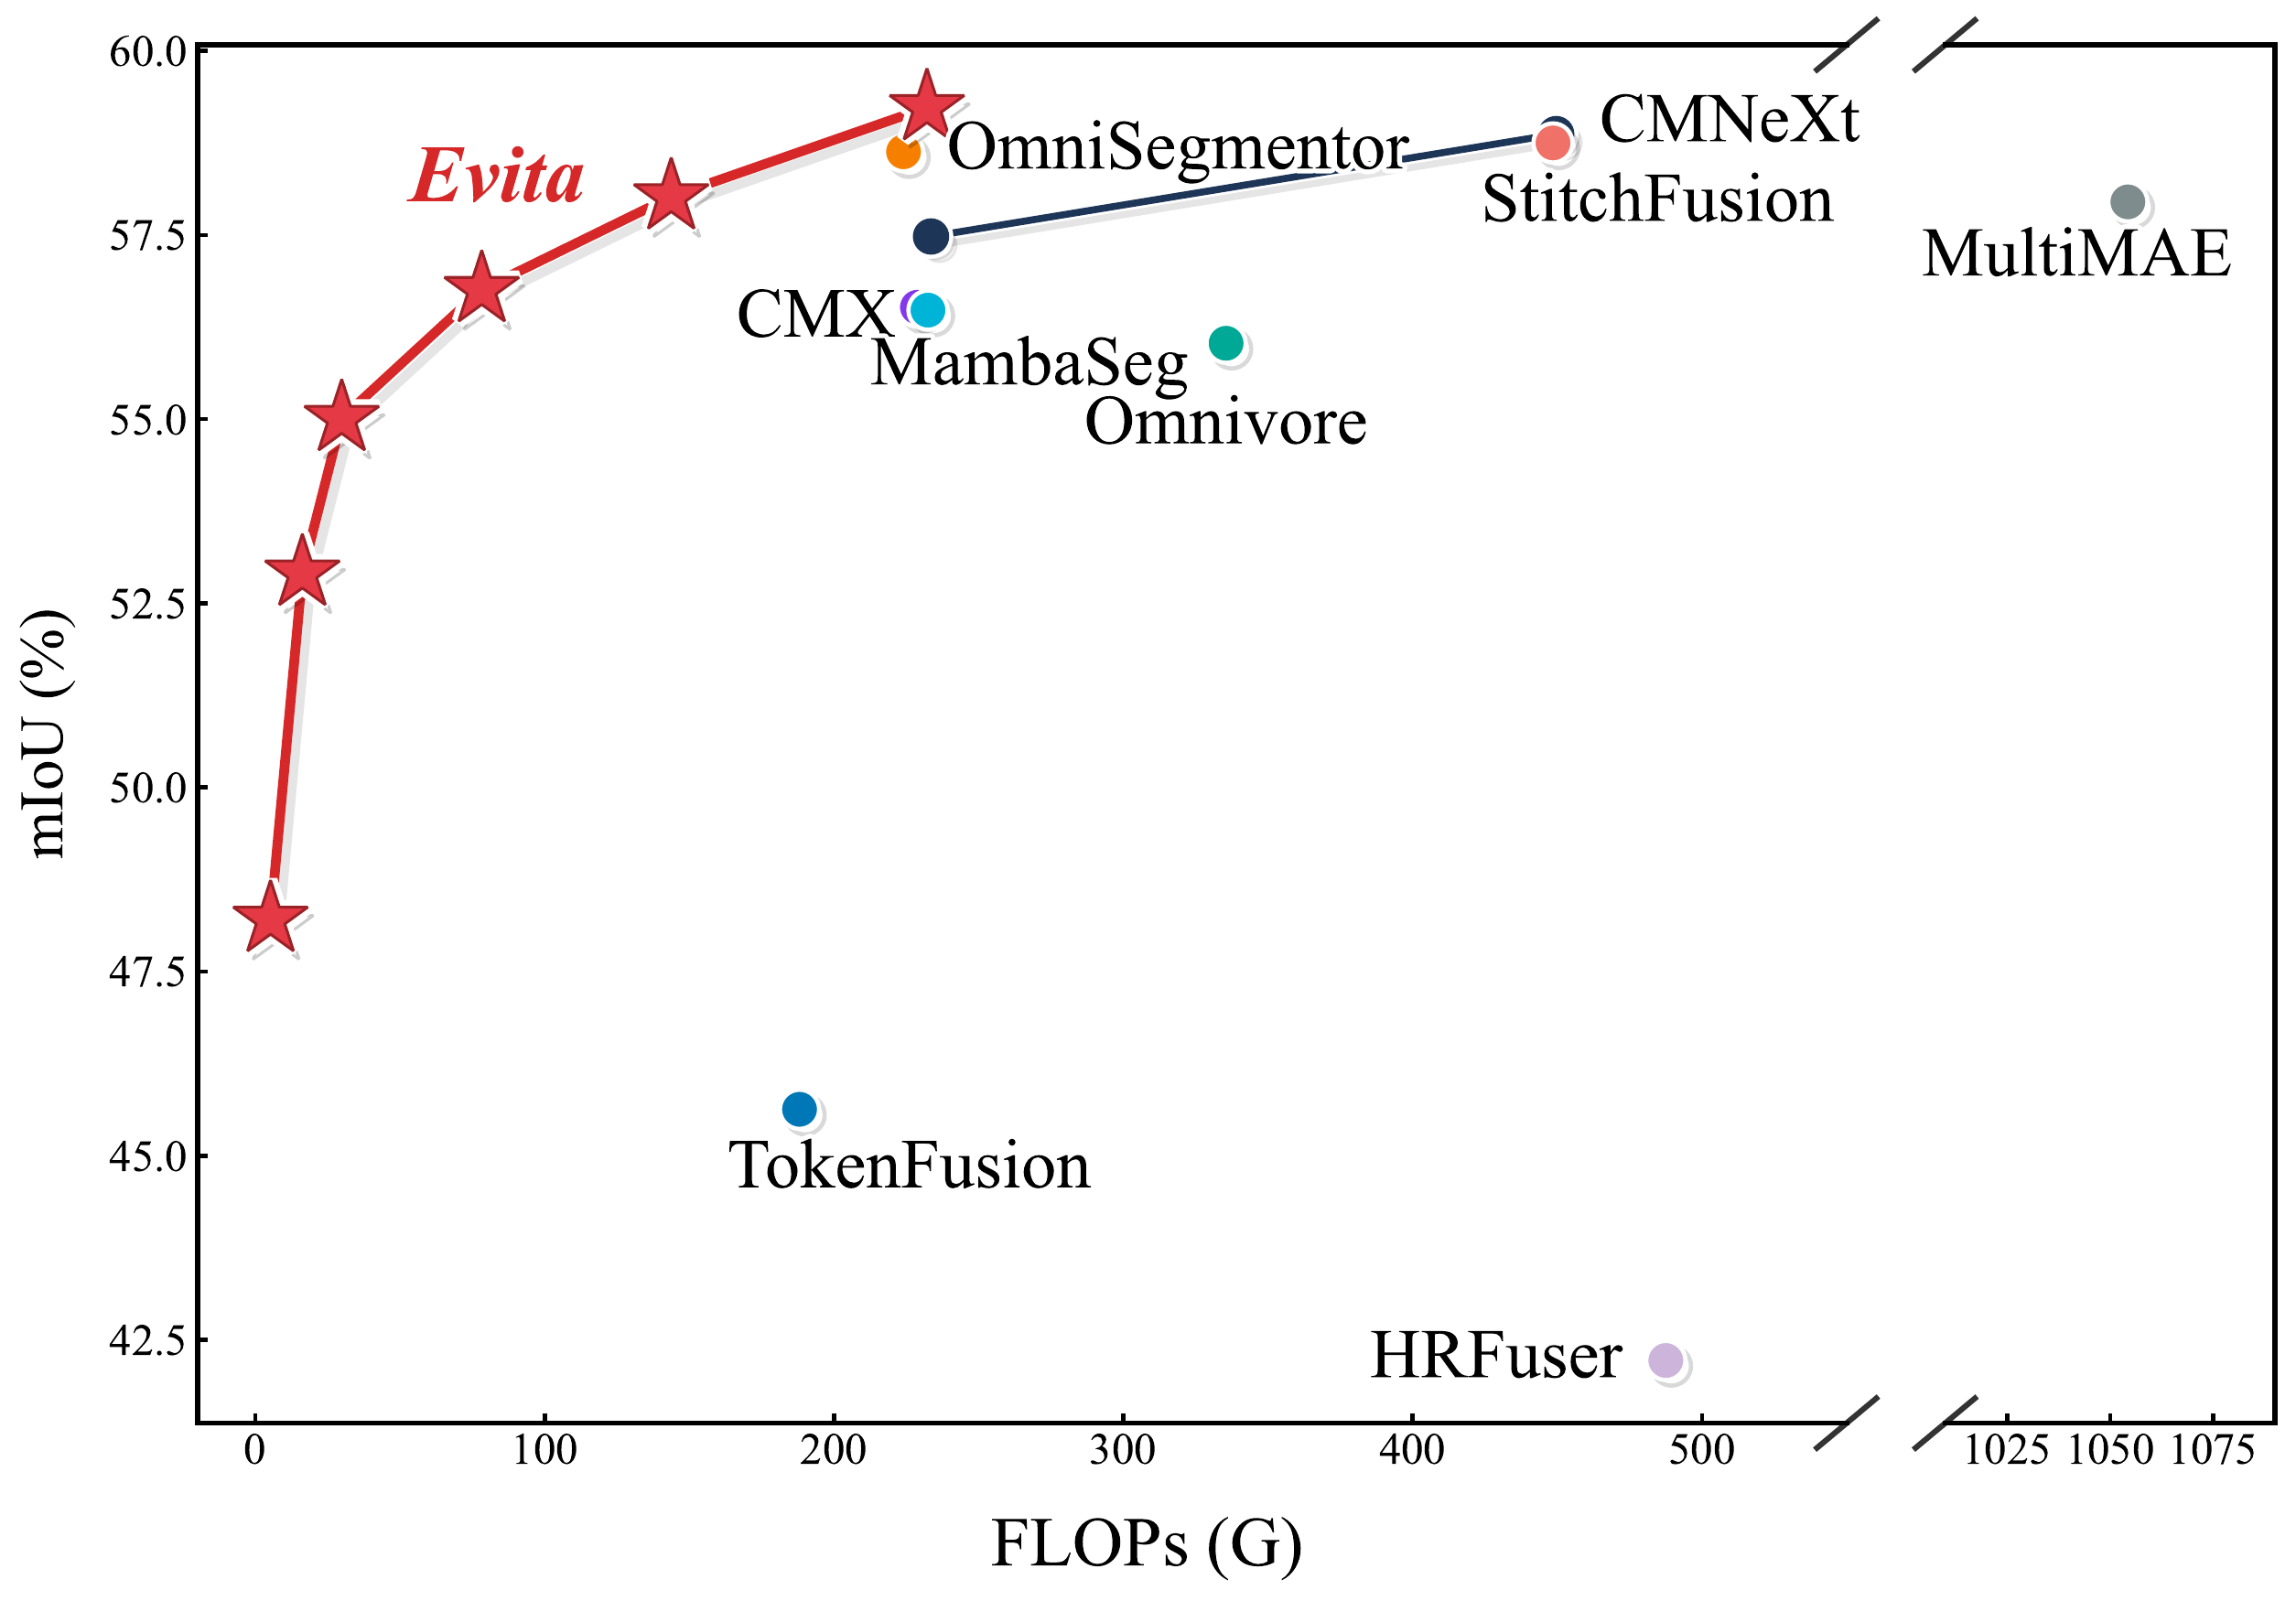
The tables summarize the reported results while omitting venue labels from the webpage. Evita variants are highlighted in blue, and the best scores are marked in red.
| Method | Backbone | Representation | Input size | Params (M) | FLOPs | mIoU (%) |
|---|---|---|---|---|---|---|
| HRFuser | HRFormer-T | EventBinary | 1024x1024 | 49.9 | 487.5 | 42.22 |
| TokenFusion | MiT-B2 | EventBinary | 1024x1024 | 26.0 | 188.05 | 45.63 |
| MultiMAE | ViT-B | EventBinary | 1024x1024 | 100.3 | 1054.3 | 57.95 |
| Omnivore | Swin-B | EventBinary | 1024x1024 | 86.7 | 335.49 | 56.03 |
| CMX | MiT-B2 | EventBinary | 1024x1024 | 66.6 | 228.8 | 56.52 |
| CMNeXt | MiT-B2 | EventBinary | 1024x1024 | 58.7 | 233.5 | 57.48 |
| CMNeXt | MiT-B4 | EventBinary | 1024x1024 | 116.5 | 449.6 | 58.87 |
| MambaSeg | VMamba-T | EventBinary | 1024x1024 | 25.5 | 232.45 | 56.48 |
| OmniSegmentor | DFormer-L | EventBinary | 1024x1024 | 39.0 | 224.0 | 58.63 |
| StitchFusion | MiT-B4 | EventBinary | 1024x1024 | 65.3 | 448.5 | 58.75 |
| Evita-P | Ours-P | EventBinary | 1024x1024 | 1.3 | 5.2 | 48.21 |
| Evita-N | Ours-N | EventBinary | 1024x1024 | 4.9 | 16.2 | 52.91 |
| Evita-T | Ours-T | EventBinary | 1024x1024 | 6.5 | 29.8 | 55.01 |
| Evita-S | Ours-S | EventBinary | 1024x1024 | 21.9 | 78.2 | 56.79 |
| Evita-B | Ours-B | EventBinary | 1024x1024 | 34.3 | 143.7 | 58.02 |
| Evita-L | Ours-L | EventBinary | 1024x1024 | 44.3 | 232.1 | 59.57 |
| Method | Backbone | Params | Modality | Rep. | DDD17 FLOPs | DDD17 mIoU | DDD17 Acc | DSEC FLOPs | DSEC mIoU | DSEC Acc |
|---|---|---|---|---|---|---|---|---|---|---|
| Single Modal Method | ||||||||||
| SegFormer | MiT-B2 | 27.5 | Image | RGB | 16.0 | 71.05 | 95.73 | 67.6 | 71.99 | 94.97 |
| SegNeXt | SegNeXt-B | 27.6 | Image | RGB | 10.2 | 71.46 | 95.97 | 40.4 | 71.55 | 94.89 |
| EV-SegNet | Xception | 34.6 | Event | 6-Channel | 8.0 | 54.81 | 89.76 | 30.6 | 51.76 | 88.61 |
| ESS | E2VID | 47.2 | Event | Voxel Grid | 51.8 | 61.37 | 91.08 | 202.6 | 51.57 | 89.25 |
| RGB-X Method | ||||||||||
| TokenFusion | MiT-B2 | 28.6 | Image-Event | Voxel Grid | 32.6 | 67.96 | 94.77 | 137.4 | 70.67 | 95.20 |
| MultiMAE | ViT-B | 89.7 | Image-Event | Voxel Grid | 56.1 | 63.31 | 93.33 | 291.5 | 67.11 | 94.35 |
| HRFuser | HRFormer-T | 12.8 | Image-Event | Voxel Grid | 17.6 | 73.17 | 95.41 | 70.0 | 59.66 | 92.76 |
| CMX | MiT-B2 | 66.6 | Image-Event | Voxel Grid | 15.7 | 77.64 | 96.46 | 62.1 | 73.88 | 95.51 |
| CMX | MiT-B3 | 106.3 | Image-Event | Voxel Grid | 23.8 | 76.83 | 96.50 | 94.1 | 73.24 | 95.40 |
| CMX | MiT-B4 | 140.0 | Image-Event | Voxel Grid | 31.5 | 77.00 | 96.36 | 124.8 | 74.06 | 95.54 |
| CMNeXt | MiT-B2 | 58.7 | Image-Event | Voxel Grid | 16.0 | 76.86 | 96.47 | 63.4 | 73.42 | 95.48 |
| CMNeXt | MiT-B4 | 116.6 | Image-Event | Voxel Grid | 31.0 | 77.70 | 96.48 | 122.3 | 73.84 | 95.49 |
| CMNeXt | MiT-B5 | 149.0 | Image-Event | Voxel Grid | 37.8 | 77.09 | 96.47 | 149.3 | 74.22 | 95.59 |
| GeminiFusion | MiT-B2 | 31.8 | Image-Event | Voxel Grid | 33.6 | 71.15 | 96.15 | 141.4 | 71.45 | 95.31 |
| StitchFusion | MiT-B2 | 30.0 | Image-Event | Voxel Grid | 20.8 | 76.83 | 96.30 | 89.7 | 73.63 | 95.43 |
| StitchFusion | MiT-B3 | 47.5 | Image-Event | Voxel Grid | 28.2 | 76.58 | 96.54 | 112.1 | 74.47 | 95.57 |
| StitchFusion | MiT-B4 | 64.4 | Image-Event | Voxel Grid | 36.0 | 77.41 | 96.50 | 143.1 | 73.69 | 95.44 |
| OmniSegmentor | DFormer-L | 40.9 | Image-Event | Voxel Grid | 25.3 | 79.34 | 96.54 | 100.7 | 75.31 | 95.74 |
| RGB-E Method | ||||||||||
| ESS | E2VID | 52.7 | Image-Event | Voxel Grid | 20.0 | 60.43 | 90.37 | 77.4 | 53.29 | 89.37 |
| EDCNet | ResNet-18 | 23.1 | Image-Event | Voxel Grid | 21.3 | 61.99 | 93.80 | 72.5 | 56.75 | 92.39 |
| HALSIE | Customed | 5.0 | Image-Event | Voxel Grid | 4.9 | 60.66 | 92.50 | 37.7 | 52.43 | 89.01 |
| SE-Adapter | ViT-B | 88.1 | Image-Event | MSP | 62.3 | 69.06 | 95.32 | 267.4 | 69.77 | 93.58 |
| EISNet | MiT-B2 | 34.4 | Image-Event | AET | 16.8 | 75.03 | 96.04 | 67.3 | 73.07 | 95.12 |
| EISNet | MiT-B3 | 95.0 | Image-Event | AET | 29.3 | 76.14 | 96.14 | 116.6 | 73.33 | 95.07 |
| EISNet | MiT-B4 | 128.5 | Image-Event | AET | 37.0 | 76.06 | 95.89 | 147.2 | 72.56 | 95.05 |
| Hybrid-Seg | ERViT-T | 2.1 | Image-Event | Voxel Grid | 4.0 | 67.31 | 95.07 | 14.4 | 66.57 | 94.27 |
| ESC | MiT-B2 | 56.9 | Image-Event | Voxel Grid | 18.3 | 76.81 | 96.35 | 95.1 | 73.55 | 95.49 |
| MambaSeg | VMamba-T | 25.4 | Image-Event | Voxel Grid | 33.8 | 77.56 | 96.33 | 159.5 | 75.10 | 95.71 |
| Evita-Pico | Ours-P | 1.3 | Image-Event | Voxel Grid | 0.6 | 71.26 | 95.78 | 2.6 | 65.55 | 94.12 |
| Evita-Nano | Ours-N | 4.9 | Image-Event | Voxel Grid | 2.3 | 74.84 | 96.17 | 9.2 | 70.09 | 94.99 |
| Evita-Tiny | Ours-T | 6.5 | Image-Event | Voxel Grid | 3.2 | 77.04 | 96.45 | 12.9 | 73.90 | 95.55 |
| Evita-Small | Ours-S | 21.9 | Image-Event | Voxel Grid | 10.3 | 78.56 | 96.72 | 40.9 | 75.07 | 95.70 |
| Evita-Base | Ours-B | 34.3 | Image-Event | Voxel Grid | 14.7 | 79.11 | 96.73 | 58.5 | 76.08 | 95.86 |
| Evita-Large | Ours-L | 44.3 | Image-Event | Voxel Grid | 20.8 | 80.12 | 96.68 | 82.7 | 76.80 | 95.97 |
@misc{peng2026evita,
  title  = {Weaving Light and Time: Unified Harmonic-Geometric Representation Learning for Dense RGB-Event Parsing},
  author = {Peng, Chenxu and Zhou, Chongtian and Liu, Dicheng and Yin, Bowen and Dai, Yimian and Liu, Xialei and Cheng, Ming-Ming and Li, Xiang},
  year   = {2026}
}